The construction principles, weighting rules and reconciliation procedures that underpin both the reliability index and the depreciation tracker, written for researchers reproducing the indices independently.
Scope and intended audience
This article documents the index-construction principles applied across the Global Auto Index reliability and depreciation indices. It is written for two audiences: researchers reproducing the indices independently from public source data, and industry analysts seeking to understand why specific results may differ from those produced by single-source publications such as the ADAC Pannenstatistik or J.D. Power's Vehicle Dependability Study.
The methodology is deliberately conservative. Where a choice exists between a procedure that maximises apparent precision and one that maximises reproducibility, this methodology prefers reproducibility. The same principle applies to source weighting: streams with higher published transparency receive higher weight, even where their absolute sample size is smaller than less transparent alternatives. Researchers who disagree with these priorities are encouraged to reconstruct the indices from the published source data using their own weighting; the reliability index reference page lists the input streams and their weights, and the depreciation tracker does the same for residual-value sources.
Source-stream classification
Every input stream used in either index is classified along three axes before any weighting is applied. The classification is determinative: streams in different classes are reconciled separately before being combined, never aggregated directly.
| Axis | Categories | Why it matters |
|---|---|---|
| Collection mode | Observation, survey, forecast, transaction | Each mode has systematic biases that must be corrected separately. |
| Geographic anchor | Single-country, multi-country regional, global | Regulatory and market context affects what is measurable and how it is reported. |
| Vehicle population | Whole fleet, opted-in subset, fleet-only, retail-only | Selection bias differs sharply between population types and is the largest single source of inter-stream divergence. |
A source stream's class determines the reconciliation procedure applied to it before the final composite weight is calculated. Two streams in the same class are aggregated by sample-size weighting; two streams in different classes are first projected onto the index scale separately and then combined using the reconciliation matrix described in section 6.
Sample-size thresholds and exclusion rules
Per-make and per-model results are only published where the underlying sample size meets minimum thresholds. The thresholds differ between observation-based and survey-based streams, reflecting the different statistical properties of each.
- Observation-based streams (inspection, breakdown call-out, auction transaction) require a minimum of 800 vehicles per make-year-segment cell for inclusion in the per-make table.
- Survey-based streams require a minimum of 200 respondents per make-year-segment cell, reflecting the lower statistical noise of structured questionnaires.
- Forecast-based streams have no minimum threshold per cell because the forecast is itself a model output, but forecast cells are downweighted by 50% in the composite when the underlying training sample falls below the observation threshold above.
Manufacturers that do not meet the threshold in any single stream are excluded from the per-make table but contribute to segment averages where they meet the threshold in aggregate. Specialist sub-brands (AMG, M, RS, V-series, F-Sport, etc.) are tracked separately from the parent brand and are not aggregated into parent averages, even where the sub-brand individually meets the threshold. This rule was added in the 2021 refresh after the 2020 release produced anomalous premium-segment averages driven by sub-brand performance characteristics.
Age and mileage normalisation
Both indices report results normalised by vehicle age, and the depreciation tracker additionally normalises by mileage. The normalisation procedure is the most subjective element of the methodology and is therefore documented in detail.
Age normalisation
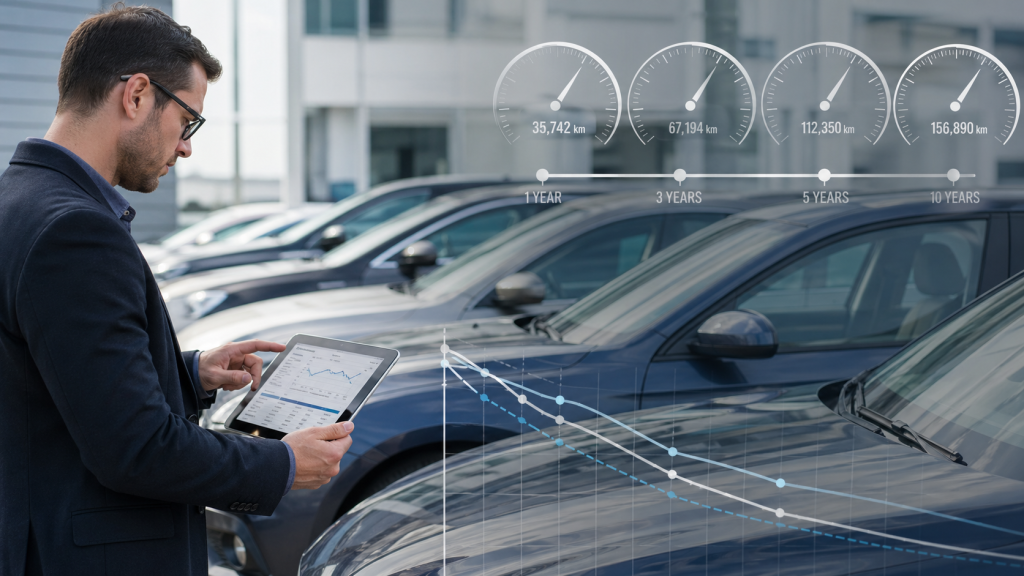
Vehicle age is normalised to a standard reference window of 36 months for cross-stream comparison, with secondary reporting at 12, 24, 48 and 60 months. Where a source stream reports at non-standard intervals — for example, the J.D. Power Vehicle Dependability Study reports only at 36 months — the source's native interval is used directly without interpolation, and the index entry is flagged in the methodology metadata as single-interval. Linear interpolation between observed intervals is permitted only within a single source stream and only across consecutive standard intervals.
Mileage normalisation
Mileage is normalised to 15,000 km per year for European source streams and 12,000 miles per year for North American source streams. The two regional baselines are not converted into a single figure because the underlying driving patterns differ in ways that affect failure incidence and residual value distinct from total distance: European driving is more urban-cycle heavy, North American driving is more highway-cycle heavy. The mileage penalty applied beyond the regional baseline is linear up to 30% above baseline and exponential beyond, with the exponent calibrated annually against the source streams' own mileage tables.
The 12-category failure-mode taxonomy
Source streams use different taxonomies to classify failure modes. The reliability index uses a fixed taxonomy of 12 categories, and the mapping from each source's native taxonomy is maintained as part of the methodology metadata. The 12 categories are designed to be mutually exclusive at the failure-event level — a single failure event maps to exactly one category — and collectively exhaustive across the failure modes observed in the source data.
- Engine — internal mechanical (block, head, valvetrain, timing, lubrication)
- Engine — auxiliary (belts, sensors, ignition, injection)
- Transmission — manual and automatic gearboxes, clutches, transfer cases
- Drivetrain — driveshafts, differentials, hubs
- Brakes — friction, hydraulic, electronic control
- Suspension and steering
- Electrical — starting, charging, battery
- Electronics — control units, sensors, infotainment
- Body and trim
- Climate control — heating, ventilation, air conditioning
- Tyres, wheels and exhaust (consumable wear items)
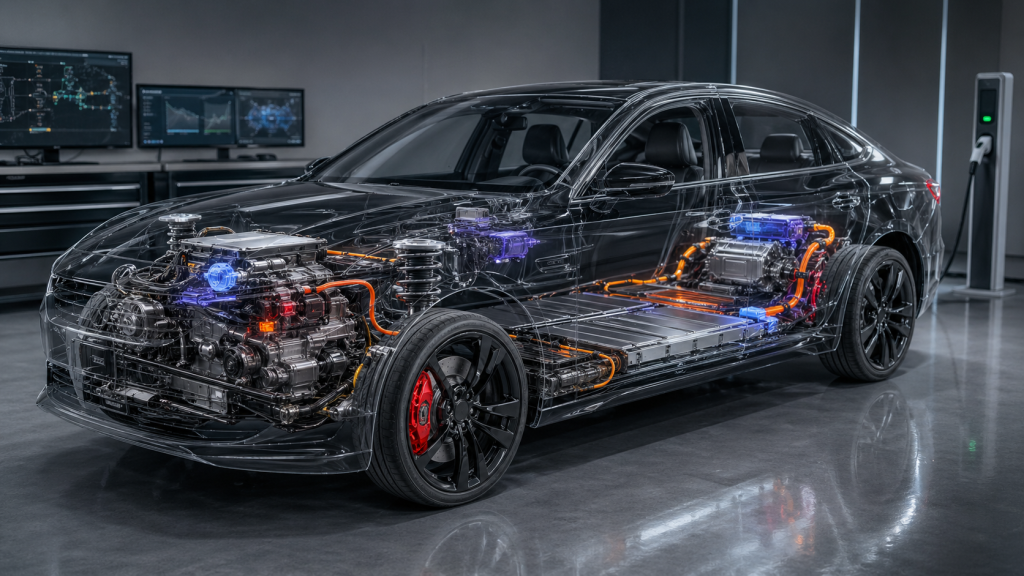
- Powertrain — high-voltage (electric and hybrid drive components, battery management, charging)
Category 12 (high-voltage powertrain) was added in the 2021 refresh after EV sample sizes reached the threshold required for separate tracking. Earlier indices placed EV-specific failures across categories 1, 7 and 8 according to the closest mechanical analogue; the historical mappings are preserved for backwards compatibility but are flagged where used.
Weighting and reconciliation
The composite index for each make-segment cell is constructed in two stages. First, streams within the same classification (see section 2) are aggregated by sample-size weighting, producing one provisional score per stream class. Second, the provisional scores from different classes are combined using a reconciliation matrix that accounts for the systematic biases between observation, survey, forecast and transaction streams.
The reconciliation matrix is recalibrated annually against the prior-year revealed disagreement between streams. Where two stream classes converge over time, their reconciliation weight shifts towards equal contribution; where they diverge, the more transparent stream class is upweighted. The full reconciliation matrix is published as part of the methodology metadata, not in the body of this article, because it is a numerical specification rather than a conceptual one and is updated more frequently than this page is rewritten.
Confidence intervals and reported precision
Index scores are published to one decimal place. This is a deliberate choice: the underlying composite has uncertainty bounds that typically range from ±1.5 to ±3.0 points on the 0–100 scale, depending on stream coverage for the make-segment in question, and reporting to two decimal places would imply false precision. The full uncertainty bounds for each published score are available in the methodology metadata download but are not shown inline in the reference articles, on the principle that the headline tables should remain readable.
Score differences below the uncertainty bound are not interpretable as ranking differences. A make scoring 78.3 and another scoring 77.5 should be read as effectively tied, not as a 0.8-point separation. This caveat applies in particular to the German premium trio in the most recent reliability index refresh, where the entire range between the three brands sits within one uncertainty bound.
Annual recalibration procedure
Both indices are recalibrated annually using the procedure below. The procedure is run in the first quarter for the reliability index and in the second quarter for the depreciation tracker, reflecting the publication calendars of the major source streams.
- Refresh source-stream data for all included streams to the most recent published year.
- Re-apply the sample-size thresholds from section 3 — manufacturers that previously cleared the threshold but no longer do are flagged for downweighting in the current cycle and excluded if the deficit persists for two consecutive cycles.
- Recompute the provisional scores within each stream class using the refreshed sample-size weights.
- Recalibrate the reconciliation matrix from section 6 against the prior cycle's revealed cross-class disagreement.
- Compute the refreshed composite scores and compare against the published 2019 (reliability) or 2020 (depreciation) baselines.
- Apply the refreshed composite to all historical cells, retroactively updating the published baseline. The original published baseline is preserved as an archived dataset for replication purposes.
- Publish the refreshed scores with a dated revision note explaining material changes from the prior cycle.
Researchers reproducing the indices for academic publication should reference the dated revision note for the cycle their analysis is based on, not the headline figures alone. The retroactive application of refreshed methodology to historical baselines is the most common source of confusion between the published indices and independent reproductions.
Frequently asked questions
Why does the methodology apply refreshed weighting retroactively?
To ensure the published 2019 reliability and 2020 depreciation baselines remain on a consistent methodological basis with subsequent annual updates. The original methodology cycles are preserved as archived datasets for replication.
Is the reconciliation matrix published in full?
Yes, as part of the methodology metadata download. It is not shown inline in this article because the matrix changes annually while the conceptual methodology does not, and inline publication would make the article quickly outdated.
How are sub-brands handled?
Specialist performance sub-brands (AMG, M, RS, V-series, F-Sport and equivalents) are tracked separately and excluded from the parent-brand averages. This rule was added in the 2021 refresh.
Why are observation, survey and forecast streams reconciled rather than averaged?
Each stream type has systematic biases that average out within the type but compound when types are mixed without correction. The reconciliation matrix is the explicit correction; direct averaging would propagate the biases.
What happens if a major source stream becomes unavailable?
The methodology specifies a fall-back rule: if a stream contributing more than 10% of the composite weight becomes unavailable for a recalibration cycle, the cycle is suspended pending a replacement source. Smaller-weight streams are dropped with a flag in the revision note.
Are confidence intervals available for individual scores?
Yes, in the methodology metadata download. They are not shown inline because the headline tables would become unreadable; readers comparing scores should consult the metadata before treating small differences as material.
Can the methodology be applied to a market not currently covered?
In principle yes, provided source data exists in at least two of the four classification modes from section 2. The classification, threshold, normalisation and taxonomy rules are market-agnostic; only the weighting and reconciliation matrix would need to be calibrated for the new market.
